Diffraction Leads Physical AI Training Data Market by Prioritizing Creator Rights

AI research labs and robotics companies face significant challenges in securing the vast amounts of video data required for physical AI training. A key issue has been the lack of proper compensation for creators, despite much of this essential content being produced by them. Addressing this gap, Diffraction, an influencer marketing and data company based in Lancaster, Ohio, is pioneering a new market for AI training data that safeguards creator rights and ensures fair compensation. The company is committed to resolving the opacity of the existing market and fostering an equitable trading environment through robust contracts, data acquisition processes, and a clear infrastructure for proving data provenance.
Growth and Challenges in the Physical AI Training Data Market
Recent advancements in AI technology, particularly in robotics, demand that machines perform practical tasks within physical environments, such as grasping tools, navigating uneven terrain, and perceiving water movement. This necessitates an immense volume of high-quality training video data. However, a significant portion of this crucial data is derived from videos routinely produced by online creators. The core issue is that these videos frequently lack proper commercial recognition, and their creators often do not receive fair compensation.
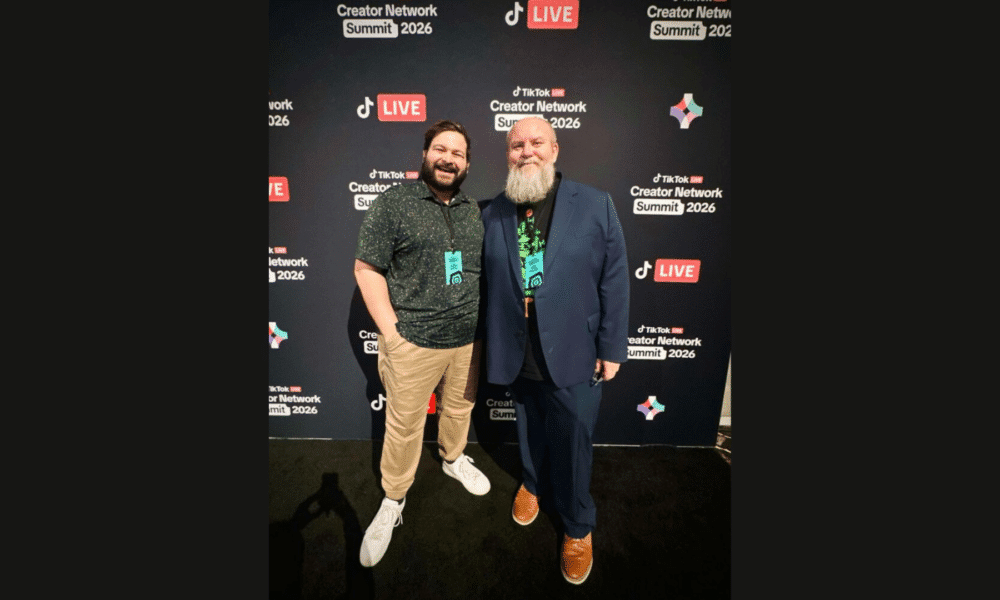
Diffraction was founded in September 2022 by co-founders Joseph Sottile and Tom Swann, launching its data layer, 'StreamGenie,' in January 2026. They recognized that while creators possess extensive video archives, they often go uncompensated when their footage is used for AI training. This realization spurred them to build a crucial link between creators and data purchasers.
Protecting Creator Rights as a Core Value
Diffraction highlights that the physical AI data market is plagued by issues of 'fraud.' Common practices such as screen recording, unauthorized extraction from public sources, or data compilation without clear rights documentation undermine the legal integrity of data sets. To counter this, Diffraction has made 'provenance' its foremost design principle, ensuring that every data set includes documentation verifying the content owner's consent and explicit grant of rights. This proactive strategy also addresses evolving regulatory landscapes, such as the EU AI Act, which, from August 2025, will require general-purpose AI model providers to disclose summaries of the content used for training.
The company's licensing terms explicitly prohibit the use and reproduction of individuals' portrait rights and the duplicate use of licensed data. Furthermore, they mandate the deletion of data once its license has expired. Diffraction also requires separate consent for copyrighted elements embedded within videos, such as background music or the appearance of third parties on camera, thereby establishing a multi-layered protection framework for creator rights.
Demand-Driven Custom Data Building and Valuation
While most of the physical AI data market operates on a 'speculative model,' accumulating vast amounts of video content and then awaiting buyers, Diffraction adopts a 'build-to-spec' approach, constructing data specifically tailored to client requirements. They have conducted over 500 content audits to identify which types of creator content generate active purchasing demand. For example, within a creator's 100GB archive, 20 hours of Lego assembly videos might possess immediate market value.
Data pricing is determined by three variables—scarcity, skill level, and diversity—ranging from a few dollars to several hundred dollars per hour. Everyday task videos, commonly found online, hold lower value. In contrast, content showcasing specific skills, such as a proficient plumber performing actual repairs, commands a higher premium. This is because AI training benefits not only from observing correct outcomes but also from discerning the differences between skilled and unskilled actions. Diffraction also addresses the misconception that creator portrait rights would be infringed, emphasizing that physical AI training data focuses on behavior and physical interactions, rather than a creator's appearance or identity.
Future Roadmap: From Archive Licensing to Teleoperation
Diffraction outlines a three-stage roadmap for its future. The first stage involves licensing existing archive videos. The second focuses on capturing custom data specifically tailored to buyer requirements. The third and final stage is 'teleoperation,' which involves remotely controlling robotic arms to generate demonstration data. This process, where humans perform tasks directly through robotic mechanisms, is considered one of the most valuable forms of input data for physical AI development.
Progressing to teleoperation will require personnel proficient with VR control interfaces and laboratory partners capable of running pilot programs. Co-founder Joseph Sottile notes that the technology used to navigate virtual environments via VR headsets can directly translate to robotic arm teleoperation. He emphasized that skilled creators, through synergy with future robotics technology, will be able to generate significant new value.
Related Stories
Haenam to Host 4th Korea Modern Pentathlon Federation President’s Cup: 800 Athletes Expected
Jeollanam-do Haenam-gun will host the 4th Korea Modern Pentathlon Federation President's Cup at Useul Sports Park from September 2 to 7, dra…
Festivals Evolve into Immersive Travel Experiences, Boosting Local Economies and Brand Marketing
Festivals worldwide are evolving beyond simple entertainment into immersive, experience-rich travel content that encourages active participa…
KGNC Secures Patent for AI-Powered ‘Koconet,’ Revolutionizing Global K-Brand Marketing
The K-Global Network Center (KGNC) has successfully registered a patent for its AI-powered global marketing platform, 'Koconet,' introducing…